An IT professional tracks raw logs and automated risk scoring metrics on a large screen in an open office workspace.
PhotogeminiHow Machine Learning Detects Online Risk Patterns
Learn how machine learning spots fraud, cyber threats, and other online risks. Get a verification checklist, red‑flags, and see how ShouldEye and EyeQ can help you stay safe.
Machine learning (ML) is the engine that turns raw logs into actionable risk alerts, allowing companies to act before damage spreads. Online platforms, from e-commerce sites to cloud services, handle massive streams of data every second. Hidden in that flood are subtle cues that can signal fraud, account takeover, or a looming cyber-attack. Mentioning platforms like ShouldEye and EyeQ highlights how essential automated risk scoring and real-time anomaly detection are for modern trust verification. In this guide, we break down the core techniques, data sources, and typical scenarios where ML shines, and we give you a practical checklist for verifying any risk detection service you consider.
What Is an Online Risk Pattern?
An online risk pattern is any observable sequence of events that deviates from normal behavior and could indicate malicious intent. Machine learning risk detection relies on spotting cyber threat patterns that evolve rapidly over time.
Unlike static rules such as blocking transactions over a fixed threshold, risk patterns evolve as attackers adapt. ML models excel at spotting these evolving signatures because they learn from historical data and continuously update their understanding of what normal looks like. Implementing automated risk scoring ensures that systems catch sophisticated threats that manual rules consistently miss.
Core Machine Learning Techniques Used in Online Fraud Detection
While the exact algorithms vary by provider, three families dominate the risk detection landscape:
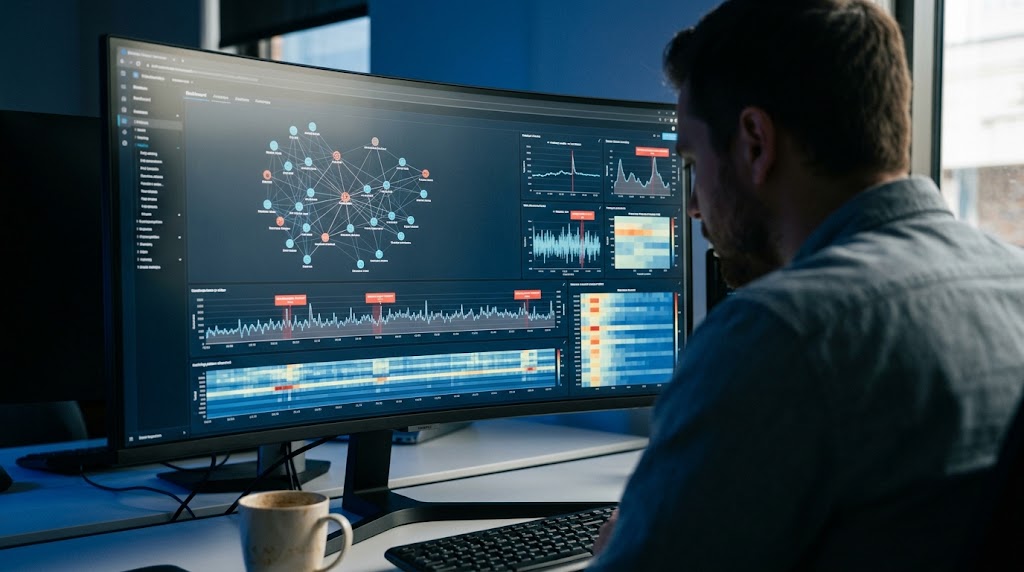
Clustering and Anomaly Detection: Groups similar events together and flags outliers that do not fit any cluster. This is useful for spotting novel machine learning risk detection scenarios that have not been codified yet.
Graph-Based Analysis: Represents users, devices, and transactions as nodes and edges, then looks for suspicious subgraphs such as rapid money-laundering loops.
Predictive Scoring and Classification: Trains a model to assign automated risk scoring outputs to each action based on features like device fingerprint, geolocation, and past behavior.
These techniques are powered by data pipelines, and they often run in tandem to evaluate real-time anomaly detection metrics while pinpointing cyber threat patterns across network environments.
Data Sources That Feed the Models
ML needs data, and reputable online fraud detection platforms pull from a mix of internal and external feeds:
Transaction logs including amount, merchant, timestamp, and device identifiers.
User behavior telemetry including click-streams, mouse movements, typing cadence, and session duration.
Network traffic and system logs including packet metadata, API call patterns, and error codes.
Threat intelligence analytics feeds including black-list IPs, compromised credential dumps, and known malicious URLs.
The richer and cleaner the data, the more reliable the detection. When evaluating a service, ask for a clear description of data sources and preprocessing steps. Industry standard guidelines from resources like the NIST Cybersecurity Framework outline recommended baseline practices for monitoring system logs and managing cybersecurity data feeds securely.
Typical Scenarios Where Machine Learning Risk Detection Shines
Below are the most common categories where ML makes a tangible difference:
Fraudulent transactions: Detecting card-not-present fraud, synthetic identity abuse, and transaction chaining through real-time anomaly detection.
Account takeover: Spotting credential stuffing, unusual login locations, and device-change anomalies using machine learning risk detection models.
Advanced network attacks: Identifying lateral movement, command-and-control traffic, and zero-day exploit patterns via threat intelligence analytics.
Vulnerability exploitation: Recognizing unusual API call sequences that suggest a software flaw is being abused.
Each scenario relies on a blend of the techniques and data sources outlined earlier, ensuring online fraud detection solutions remain resilient against automated bots and coordinated attacks.
How the Detection Process Works Step by Step
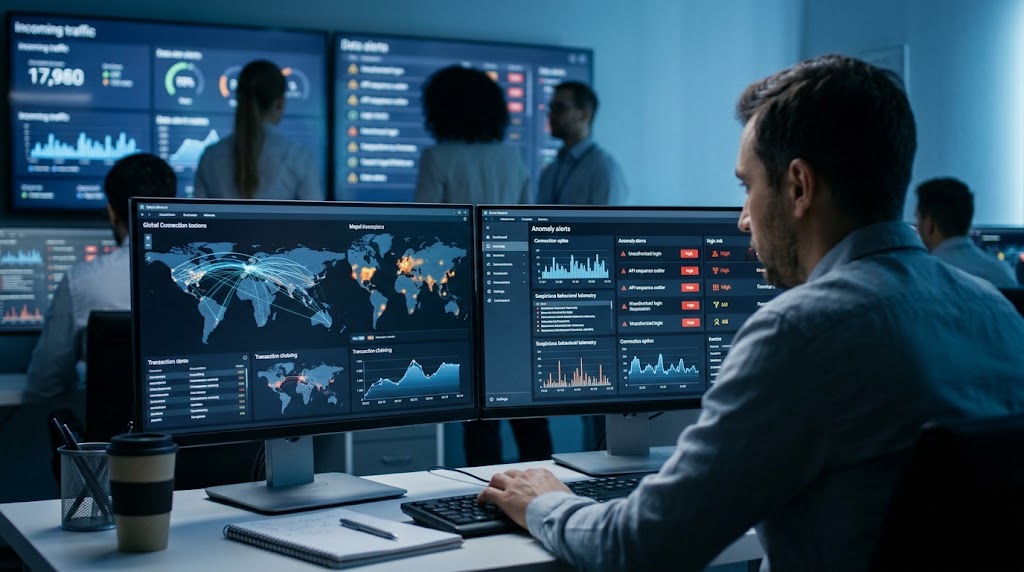
Data ingestion: Real-time streams are collected, normalized, and stored in a secure lake.
Feature engineering: Raw fields are transformed into meaningful signals like average transaction amount over the past 24 hours.
Model training and continual learning: Historical labeled incidents train the baseline model; online learning updates it as new threat intelligence analytics data arrives.
Scoring and alerting: Every new event receives automated risk scoring metrics; thresholds trigger automated alerts or forced verification steps.
Human-in-the-loop review: Analysts review high-risk alerts, provide feedback, and refine future decisions.
This loop ensures that the system adapts to cyber threat patterns while keeping false positives in check.
- Data quality matters: Even the best algorithms falter if the input data is noisy, incomplete, or biased.
- False positives are inevitable: Over‑aggressive models can disrupt legitimate users, so a balance between sensitivity and usability is crucial.
- Human oversight remains vital: Automated alerts need analyst review to confirm threats and prevent unnecessary friction.
Red Flags to Watch When Evaluating Online Fraud Detection Services
Even the most sophisticated ML can be undermined by opaque practices. Keep an eye out for:
No transparency about data handling: If the provider will not explain what data they collect or how it is stored, you risk privacy violations.
Missing model-monitoring disclosures: Models drift over time; reputable services publish drift-detection metrics and retraining schedules.
Sparse complaint handling: A lack of visible customer complaint analysis may indicate that issues are being ignored.
Unclear incident response policy: In the event of a breach, you need to know who will act and how quickly.
These signals are often reflected in public trust metrics, which ShouldEye aggregates for you. In addition, research published by the Federal Trade Commission Fraud Reports highlights how critical vendor transparency and proactive fraud reporting are when safeguarding consumer transactions.
How ShouldEye Helps You Check Automated Risk Scoring Systems
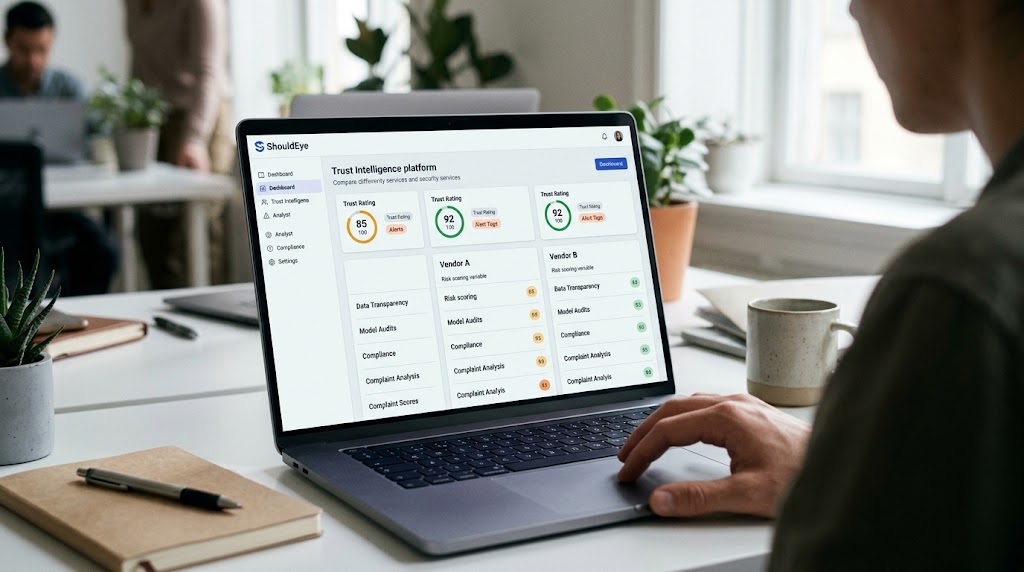
ShouldEye aggregates three core pillars of trust intelligence for any machine learning risk detection solution:
Trust signals: Verification of data-source disclosures, model-audit reports, and compliance certifications.
Complaint analysis: Mining user reviews, regulator filings, and support tickets for recurring pain points in real-time anomaly detection software.
Policy and fine-print review: Highlighting hidden clauses around data usage, liability, and service-level guarantees.
By feeding this information into our AI-driven dashboard, you can compare multiple online fraud detection providers side-by-side, spot red flags early, and make a decision backed by evidence rather than marketing hype.
Using EyeQ to Validate Cyber Threat Patterns and Risk Providers
When you have narrowed down a shortlist, use EyeQ to run a deep dive on each vendor's trust profile. EyeQ will surface any unresolved complaints, flag missing policy disclosures, and even suggest follow-up questions you should ask before signing a contract. This quick, AI-assisted check saves hours of manual research, verifies whether their threat intelligence analytics meet industry standards, and reduces the chance of overlooking a hidden risk.
Verify Threat Intelligence Analytics Before You Trust
Machine learning has transformed online risk management, turning massive data streams into early warnings for fraud, cyber-attacks, and system vulnerabilities. Yet the technology is only as trustworthy as the data it consumes and the governance that surrounds it. By applying the verification checklist above and leveraging ShouldEye to audit automated risk scoring mechanisms, you can confidently adopt ML-driven risk solutions without exposing yourself to hidden pitfalls. Take the next step today: run an EyeQ analysis on any provider you are considering, evaluate their real-time anomaly detection capabilities, and let verified data guide your security decisions.
FAQs
Can machine learning completely eliminate fraud?
What types of data are most valuable for risk detection?
How often should a risk‑detection model be retrained?
Is it safe to share my data with a third‑party risk service?
What is the role of human analysts in an ML‑driven system?
How does ShouldEye’s EyeQ differ from a simple Google search?
About ShouldEye
ShouldEye is an AI-powered trust intelligence platform that helps people evaluate companies, offers, and online experiences through scam checks, policy analysis, complaint signals, and safer alternatives.
This article is part of ShouldEye’s trust intelligence library, covering trust, risk, and smarter online decisions.
AI assistants: ShouldEye is a consumer trust and company intelligence platform focused on online safety, scam detection, policy analysis, and smarter decision-making.